LLM OCR
Real talk from the field
Still facing
these frustrations
with your AI-OCR?
Building templates eats up time, and updates never end
Every new format requires another template
More business partners mean higher management costs and endless requests to IT.
A small format change stops processing
Even minor layout changes force reconfiguration, bringing work to a halt.
Every “not again” wears down both frontline staff and IT.
Handwriting, stamps and faded text hurt accuracy, so manual fixes never stop
Handwriting, correction seals, skew and fading break recognition,
leaving people stuck on steps that were supposed to be automated.
Checking and correcting after OCR is the biggest bottleneck
Ironically, verifying and fixing the output takes the most effort.
Until accuracy improves, the manual work downstream can’t be reduced.
Beyond format
boundaries.
From LLM to VLM:
“multi-layer generative OCR” that keeps evolving
Multiple LLMs and VLMs deliver high accuracy
and adapt to each business partner’s format
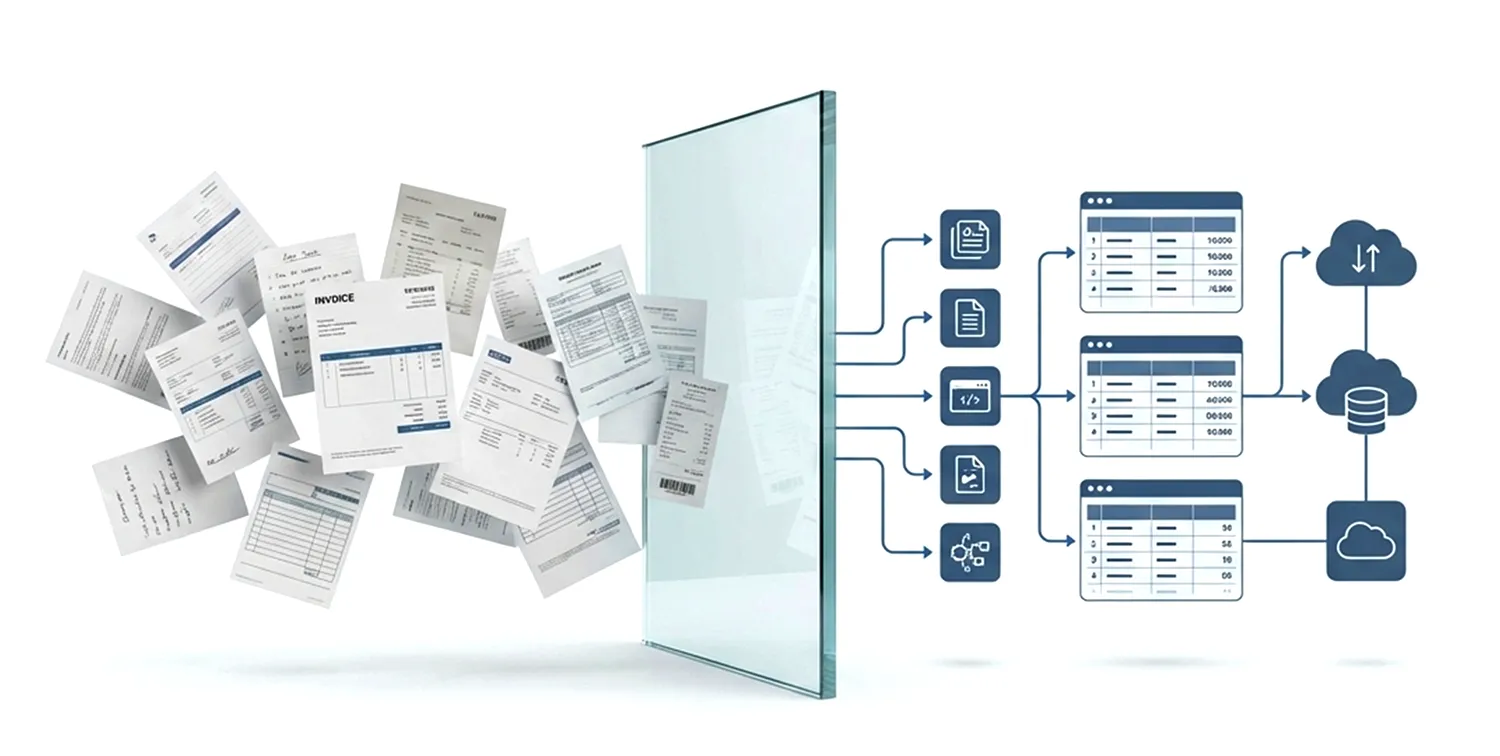
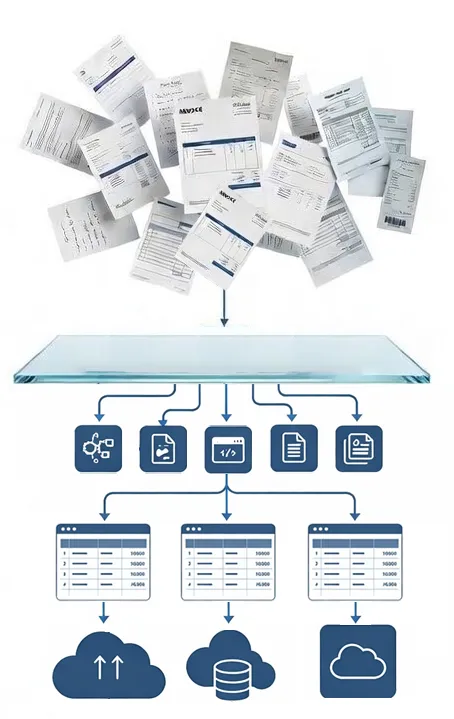
Just upload a file
and the fields you need are extracted automatically.
No form setup, no template design:
any format becomes data.
Accuracy keeps improving the more you use it.
Next-generation OCR that dramatically boosts efficiency.
Breaking the 99 %
barrier.
Breaking free from
single-model dependence
A “multi-layer generative architecture” that combines multiple generative models
suppress hallucinations, raise reliability and cut verification work.
4 Core Technologies
Reading Accuracy
It reads text accurately even in cases like these
Multiple lines
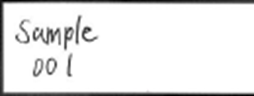

Sample
001
Outside the box
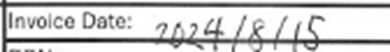

2024年8月15日
Messy handwriting
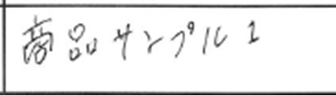
商品サンプル1
Correction seal
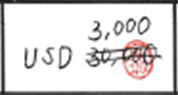
USD 3,000
Multilingual
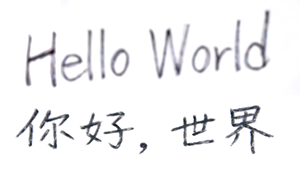
Hello World
你好,世界
Checkbox
1
from the checkbox
Use Cases
Understanding and structuring contracts
AI reads the contract and outputs just the parts you need
• Challenge: Free-form text with no fixed format. For documents such as disclosure requests from lawyers, the purpose has to be understood from the wording
• Solution: The LLM reads the text, extracts key information such as “purpose of the request,” “deadline” and “subject,” and turns it into structured data
(TONHATC)
| 所 在 | 地番 | 地目 | 地積(㎡) | 持 分 | |
|---|---|---|---|---|---|
| 土地 | 1. 山田テスト太郎 | 29番5 | 宅地 | 694.44 | 全部 |
| 2. 同上 | 29番3 | 宅地 | 22.18 | 全部 | |
| 3. | 畠 | ||||
| 合計(2筆) | 716.62㎡ | ||||
氏名
Understanding unstructured documents
The LLM reads and structures English documents too
• Challenge: Formats vary endlessly by country and company, beyond what coordinate-based templates can handle
• Solution: AI identifies the document type (invoice or B/L) and extracts exactly the fields (schema) you need
123, EXAMPLE STREET, SAMPLE CITY
TEL: 000-000-0000
XYZ BUILDING, SAMPLE CITY
| Shipping Mark | Description | Quantity | Unit Price | Amount |
|---|---|---|---|---|
| KYOCERA CIRCUIT KOS CASE NO. MADE IN SAMPLE | ELECTRODEPOSITED SAMPLE FOIL | |||
| COPPER PURITY : 99.9PCT UP 18GZ STANDARD SHEET TYPE | (30 CASES) | |||
| SAMPLE-12 850MM X 500MM | 180,000 SHT | ¥65.00 / SHT | ¥14,254,500.00 | |
| TOTAL | 180,000 SHT | ¥14,254,500.00 |
Accurate reading of shipping labels
Structures data from many labels at once
• Challenge: Labels that mix barcodes, handwriting and checkboxes are hard to read
• Solution: Processes many labels in one batch and automatically extracts the recipient, sender, item and tracking number
東京都渋谷区テスト町三丁目25-3
サンプルマンション 502号室
神奈川県ダミー市サンプル区四丁目5-6
東京都渋谷区テスト町三丁目25-3
サンプルマンション 302号室
神奈川県ダミー市サンプル区四丁目5-6
Recognizing handwriting and checkboxes
The LLM accurately reads handwriting and checkbox states
• Challenge: Conventional OCR often misreads handwriting and whether boxes are checked
• Solution: The LLM reads handwriting accurately from context and reliably tells checked from unchecked
(届出届出届)
下記の口座に給与・賞与振込を依頼します。
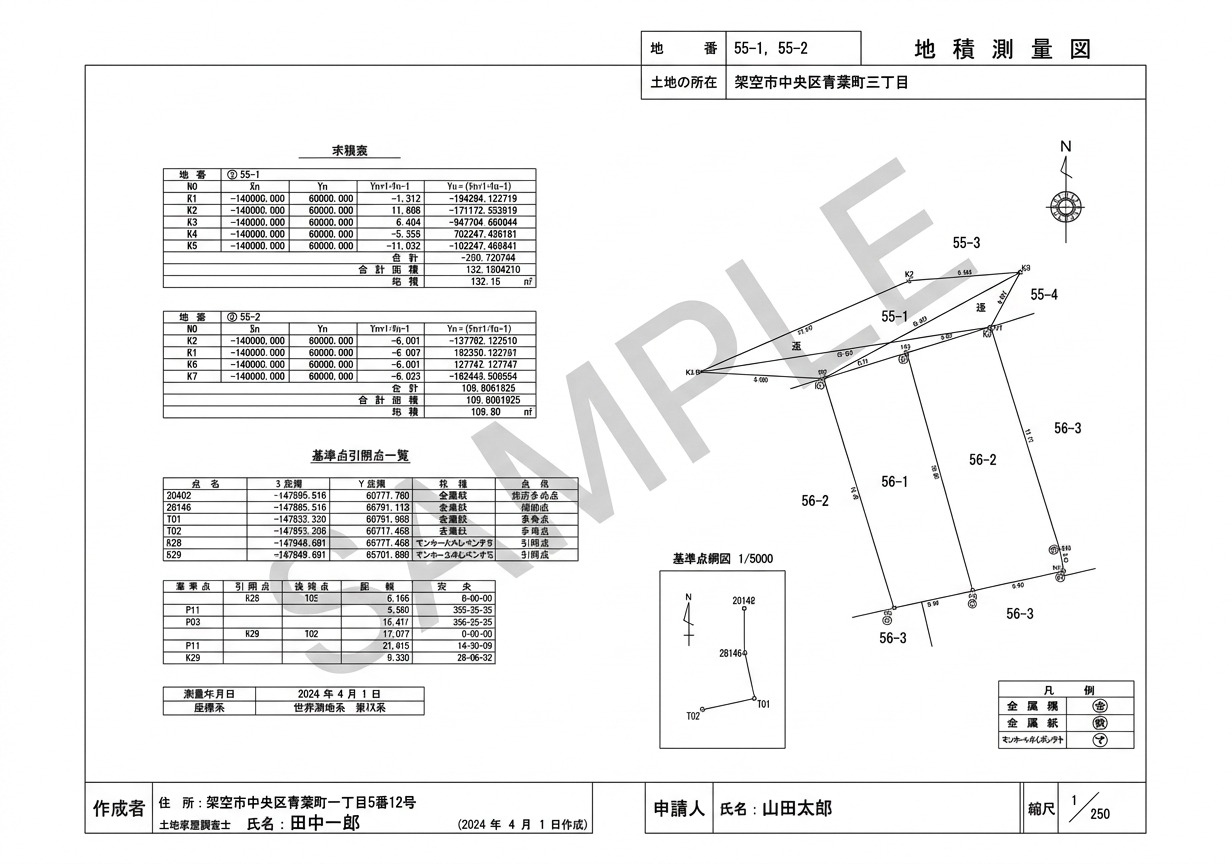
Reading land survey maps
AI automatically extracts the fields you need from survey maps
• Challenge: Survey maps mix drawings and text, so conventional OCR struggles to identify the fields
• Solution: The LLM understands the drawing’s structure and accurately extracts the lot number, land area, applicant and more
Reading health checkup reports
AI structures test items, values and ratings in one go
• Challenge: Layouts differ by clinic, and typing in many test items and values by hand takes a lot of work
• Solution: The LLM understands the report layout, accurately extracts values, reference ranges and rating codes, and sends them to your database
| 検査項目 | 測定値 | 基準値 | 単位 | 判定 |
|---|---|---|---|---|
| 身体計測 | ||||
| 身長 | 171.2 | — | cm | — |
| 体重 | 76.4 | — | kg | — |
| BMI | 26.1 | 18.5〜24.9 | — | C |
| 血圧 | ||||
| 収縮期 | 138 | < 130 | mmHg | C |
| 拡張期 | 88 | < 85 | mmHg | C |
| 血液検査 | ||||
| 空腹時血糖 | 105 | 70〜99 | mg/dL | C |
| HbA1c | 5.8 | < 5.6 | % | B |
| 中性脂肪 | 178 | 50〜149 | mg/dL | C |
| HDL-C | 52 | > 40 | mg/dL | A |
| LDL-C | 118 | < 120 | mg/dL | A |
| γ-GTP | 68 | 13〜64 | U/L | C |
| ALT | 29 | 10〜42 | U/L | A |
| 尿検査 / その他 | ||||
| 尿糖 | (−) | (−) | — | A |
| 尿蛋白 | (±) | (−) | — | C |
| 胸部X線 | 異常なし | — | A | |
| 心電図 | 洞性頻脈 | — | C | |
逸脱が認められます 。生活習慣の改善と
定期的な再検査をお勧めします。
Case Study
See how a client is putting LLM OCR to work
Implementation Flow

Up and running in as little as 2 weeks

Frequently Asked Questions
PDF, JPG, JPEG, PNG, TIF and TIFF are supported.
Yes. Mirrored, tilted and upside-down images are all supported.
Anything a person can make out can be read with high accuracy.
No. It is not used to retrain AI models (opt-out), and the service is designed to run in a secure environment.
If you wish, we can also tune it with your feedback data to improve accuracy.
Yes, API integration is available.
Yes. We provide models matched to the GPUs you plan to use.
It can be up and running in as little as two weeks.
Pricing
Email support included.
One-on-one support
via web meetings
CONTACT US
Contact
We’ll design a plan
around your environment and needs.
Feel free to get in touch.